Next Generation Genomic Analysis with Spark and ADAM
Data deluge from Next Gen Sequencing
- 1 Human Genome = 3.2 billion base pairs (bps)
- Assembled from fragments of 100 to 250bps
- 60X replication of genome needed for statistical soundness
- so 1.4 billion fragments gives you ~200GB of data
All that for about $1000
- Then, alignment against a reference (for humans and a few model organisms)
- Pipelines take that 200GB input >> 1 - 3 GB output
But, what does it all mean?
- This is the question scientists would like to spend time on.
- But current pipelines can take days.
- There is a need to seperate methods from computation.
- Still the early days of genomic sciences.
Many more sequencing opportunities
- De novo assembly of new species
- *biome
- RNAseq
Current pipeline
- Many command line tools chained together.
- Intermediate files written to disk.
Genome Analysis Tool Kit
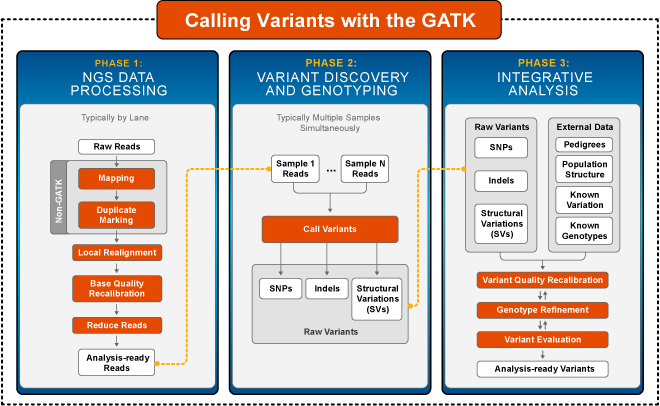
Next Gen Analysis for Next Gen Sequencing
ADAM applies some good old fashioned computer science to speed up the process.
- Amplab goals for the ADAM project - Overview paper
- from custom file formats to schema
- from flat files and RDMS to columnar storage systems
- move to in-memory computation
- easy to do distributed computation
Latest paper
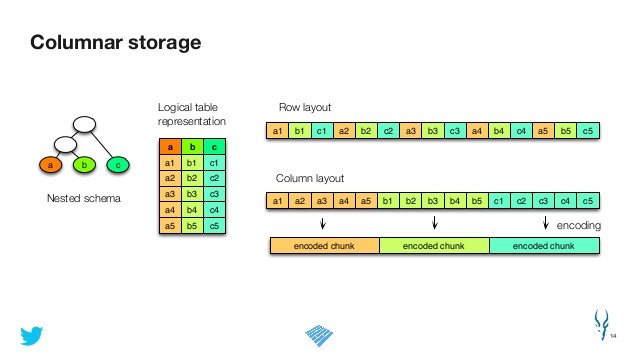
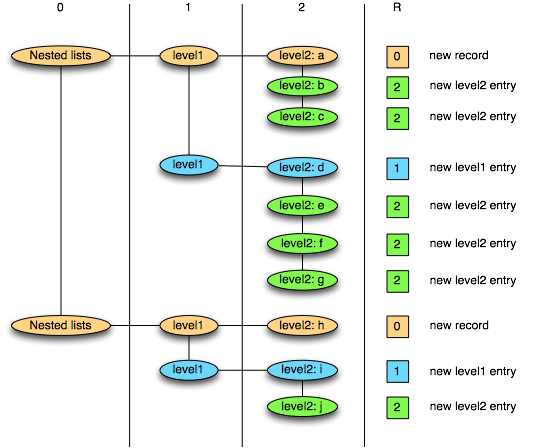
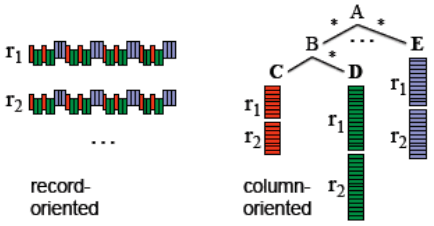
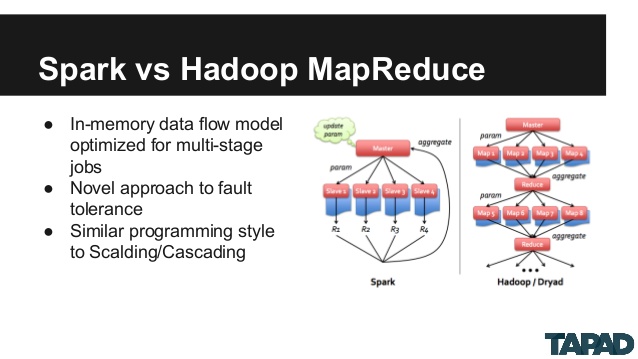
Distributed In-Memory Computation with Apache Spark
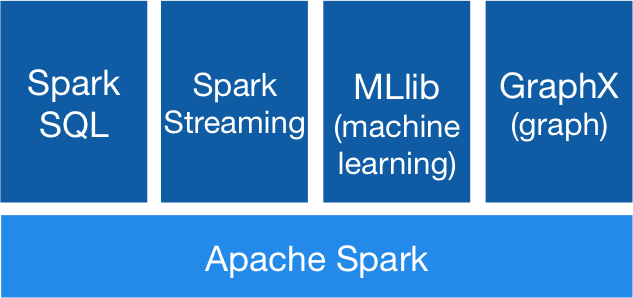
Sweet Tools Available in Spark Ecosystem
So the scientists can finally get back to the important bits.
They say it better than I ever could
To continue
Sign up for a cloud account:
- Amazon has plenty of walkthroughs and makes it easy to start down their primrose path, but why not listen to this guy
- Microsoft Azure will surely be the darling of enterprise.
- Or stick with the propeller heads
Here is a script to install ADAM for further exploration (test run on Ubuntu 14.04 LTS server)
git clone https://github.com/5x5x5x5/ADAMstartup.git